
The Boring News
// A boring, system-design focused tech news aggregator built with Next.js 16, Gemini AI API, Neon Postgres, and RSS ingestion.
The Problem
Why_Software?
Developers are flooded with tech updates scattered across blogs, changelogs, newsletters, and news sites. Most feeds either optimize for engagement or aesthetics, not for reliability, deduplication, or explainable architecture. I wanted a 'boring', infrastructure-first news layer: something that treats ingestion, storage, and query paths as first-class citizens, while exposing a simple, distraction-free UI for discovering high-signal articles.
System Design
Architecture && Flow
The architecture unifies UI and backend logic in a single Next.js 16 monolith. A background worker ingests/normalizes RSS feeds into a Neon Postgres database (Write Path), while Server Actions execute parameterized SQL queries to serve a cached, searchable feed (Read Path). Strict layer separation (`app/`, `lib/`, `db/`) keeps the system maintainable.

Implementation Details
Lightweight SQL Wrapper for Neon
// Instead of pulling in a heavy ORM, the project uses a small `sql` helper around `@neondatabase/serverless`. It supports both template literal usage (`sql\`SELECT * FROM articles WHERE id = ${id}\``) and plain string queries (`sql(text, ...params)`), while always emitting parameterized SQL.
// lib/db.ts
import { neon } from '@neondatabase/serverless';

const sqlClient = neon(process.env.DATABASE_URL!);

export async function sql(
  strings: TemplateStringsArray | string,
  ...values: any[]
) {
  // Allow either sql("SELECT ...", param1, param2) or sql`SELECT ... WHERE id = ${id}`
  if (typeof strings === 'string') {
    const result = await (sqlClient as any).query(strings, values);
    return { rows: result, rowCount: result.length };
  }

  // Build parameterized SQL from template literal
  let text = strings[0];
  for (let i = 1; i < strings.length; i++) {
    text += '$' + i + strings[i];
  }

  const result = await (sqlClient as any).query(text, values);
  return { rows: result, rowCount: result.length };
}
Searchable, Paginated Feed via Server Actions
// The main feed is powered by a server action that builds SQL conditionally based on filters, applies `ILIKE` search on titles and summaries, and uses a `limit + 1` strategy to compute `hasMore` for infinite scrolling without an extra COUNT query.
// lib/actions.ts
export interface GetArticlesParams {
  limit?: number;
  offset?: number;
  category?: string;
  search?: string;
}

export async function getArticles(
  params: GetArticlesParams = {}
): Promise<{ articles: ArticleWithSource[]; hasMore: boolean }> {
  const { limit = 30, offset = 0, category, search } = params;

  const conditions: string[] = [];
  const values: any[] = [];
  let paramIndex = 1;

  const addParam = (val: any) => {
    values.push(val);
    return '$' + paramIndex++;
  };

  if (category) {
    conditions.push(`a.id IN (
      SELECT a2.id
      FROM articles a2
      JOIN article_categories ac2 ON a2.id = ac2.article_id
      JOIN categories c2 ON ac2.category_id = c2.id
      WHERE c2.name = ${addParam(category)}
    )`);
  }

  if (search) {
    const patternIndex = paramIndex++;
    values.push('%' + search + '%');
    conditions.push(`(a.title ILIKE $${patternIndex} OR a.summary ILIKE $${patternIndex})`);
  }

  const whereClause = conditions.length ? 'WHERE ' + conditions.join(' AND ') : '';
  const queryText = `
    SELECT ...
    FROM articles a
    JOIN sources s ON a.source_id = s.id
    LEFT JOIN article_categories ac ON a.id = ac.article_id
    LEFT JOIN categories c ON ac.category_id = c.id
    ${whereClause}
    GROUP BY a.id, s.id
    ORDER BY a.published_at DESC
    LIMIT ${addParam(limit + 1)}
    OFFSET ${addParam(offset)}
  `;

  const result = await sql(queryText, ...values);
  const articles = (result.rows as ArticleWithSource[]) ?? [];
  const hasMore = articles.length > limit;

  return {
    articles: hasMore ? articles.slice(0, limit) : articles,
    hasMore,
  };
}Trade-offs
Consequences()
Operational Overhead
Using a real DB and ingest pipeline adds complexity (cron jobs, connection pooling) compared to a static site.
Necessary for dynamic search and keeping data fresh without rebuilding the site.
Search Implementation
Simple ILIKE filters are less powerful than dedicated search engines (Elastic/Algolia).
Sufficient for the current scale and keeps the 'boring' stack simple and cheap.
Content Dependency
Storing only metadata means users depend on upstream sites being online.
Respects publisher content rights and drastically reduces legal/storage risks.
Operating the News Aggregator
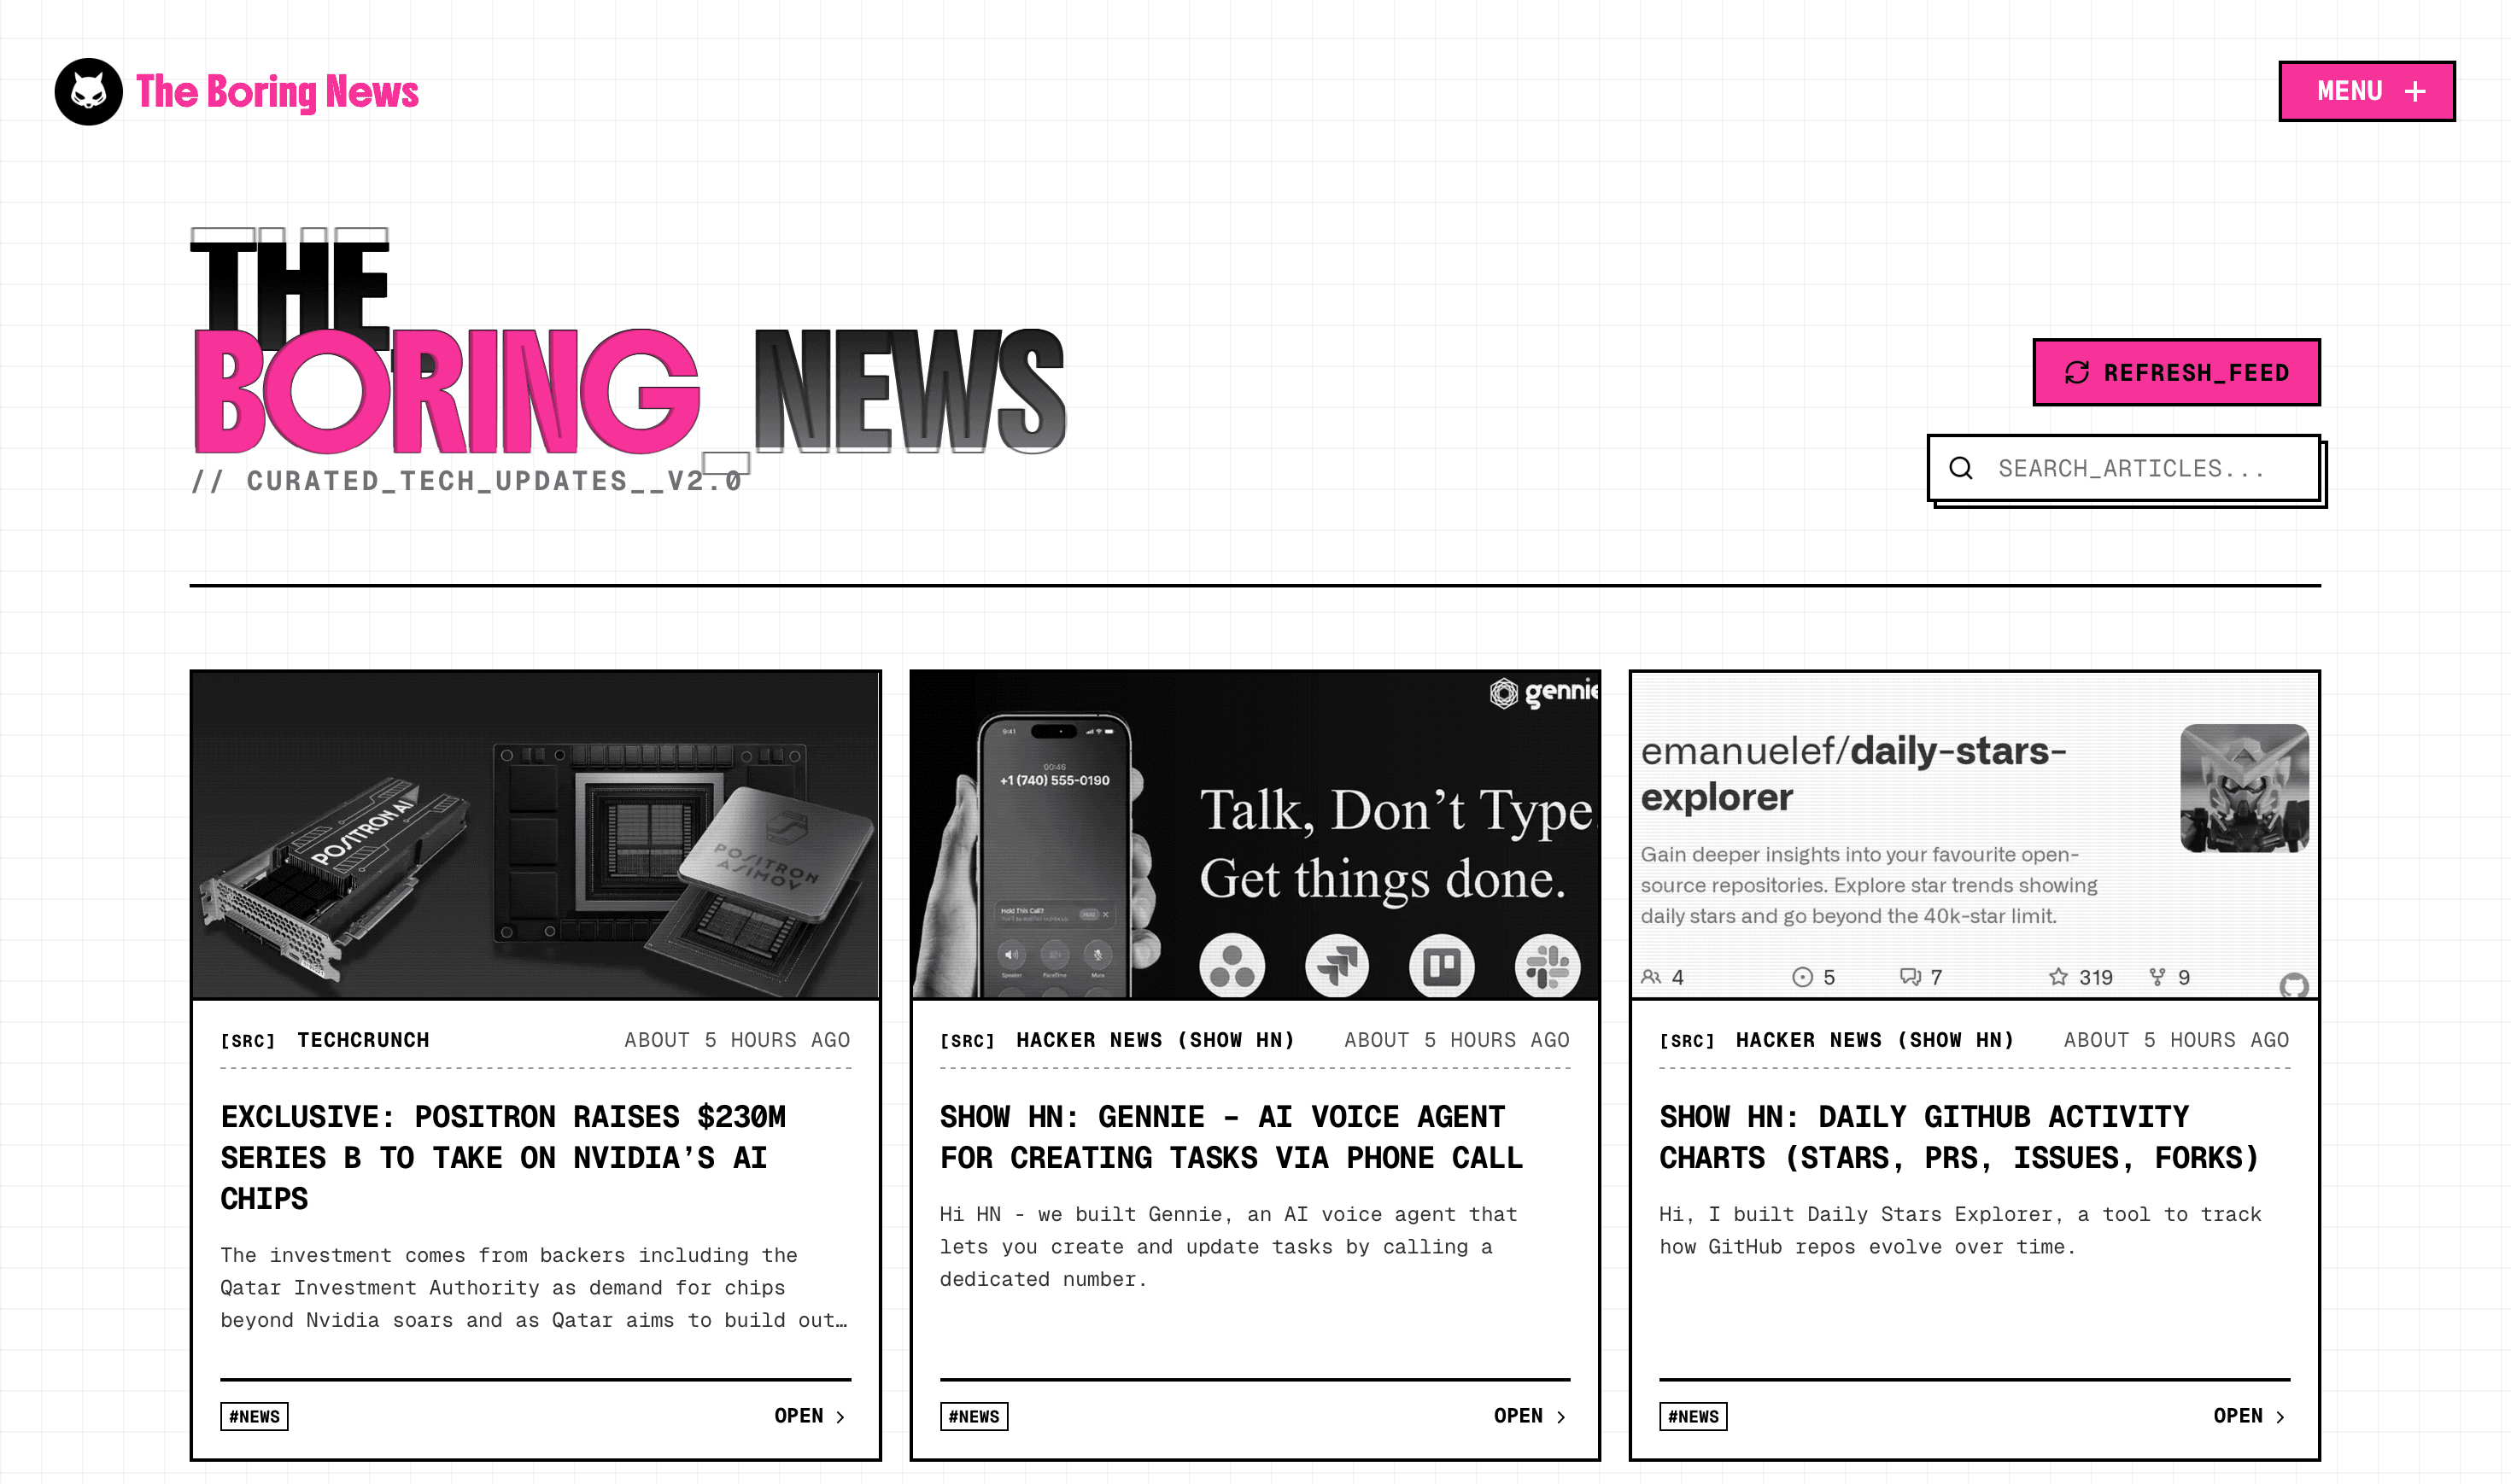
Step 1:Navigate to the main page and Browse the news
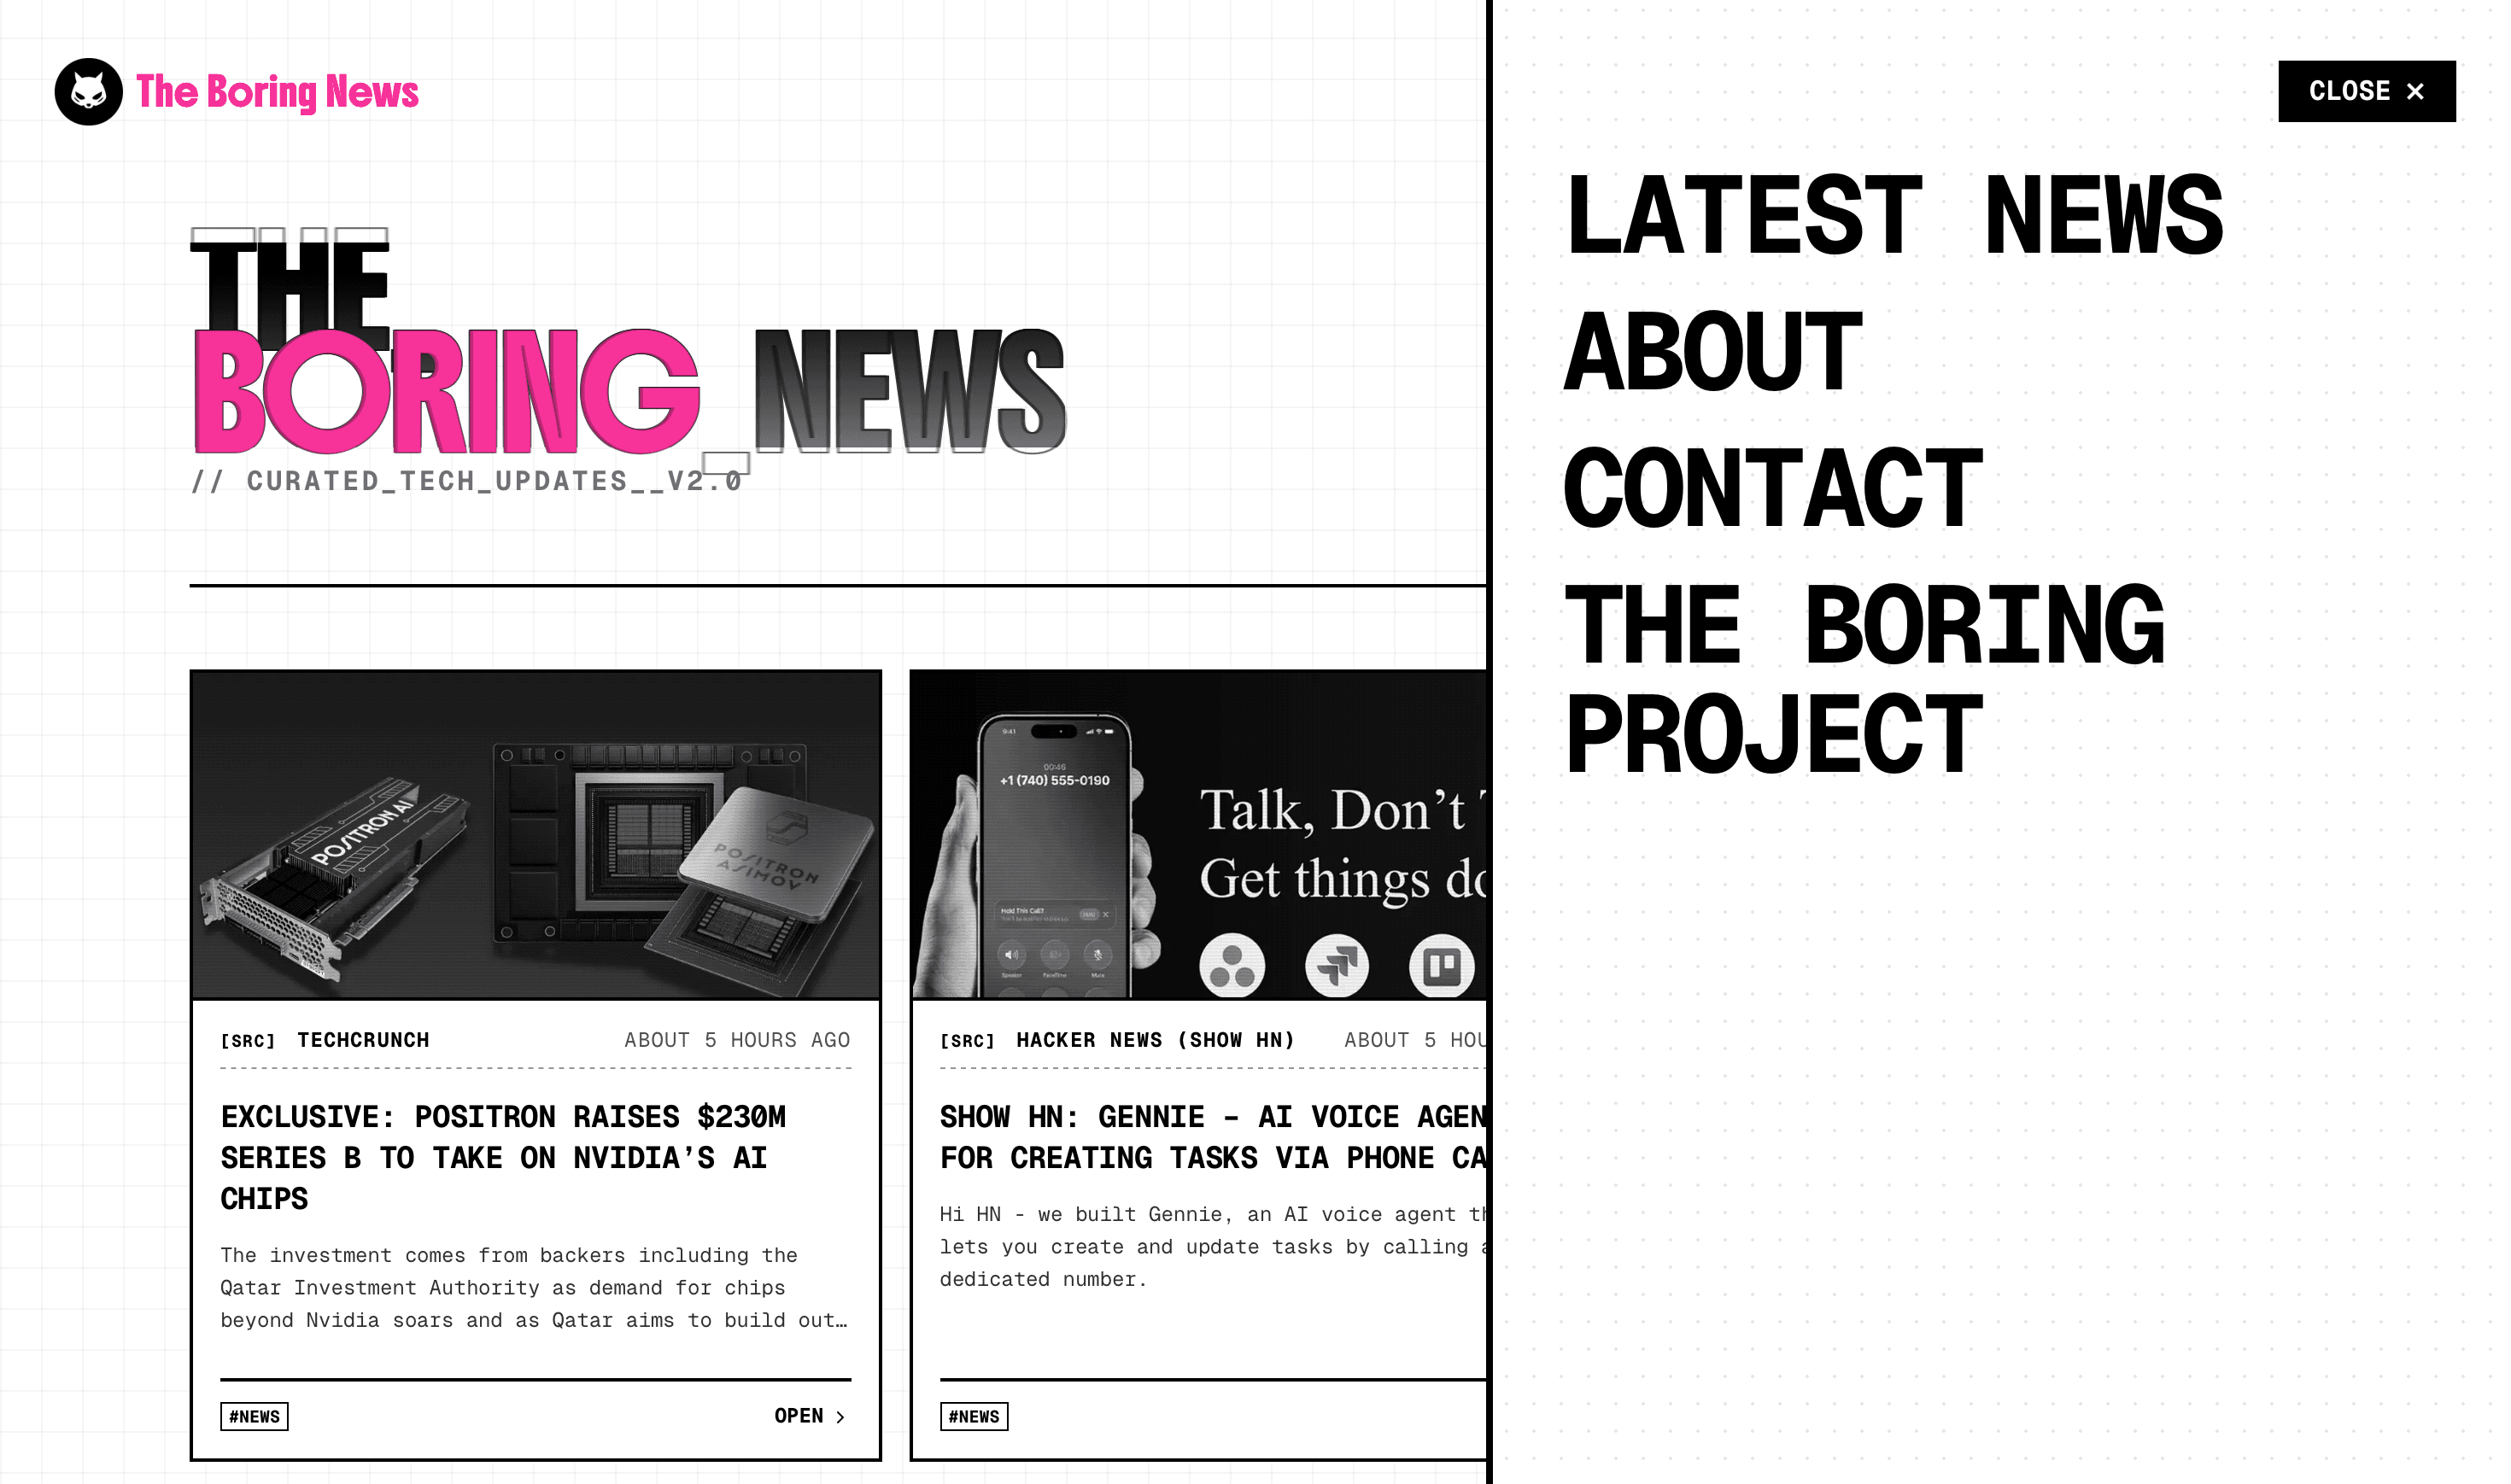
Step 2:Click on the menu to explore other sections
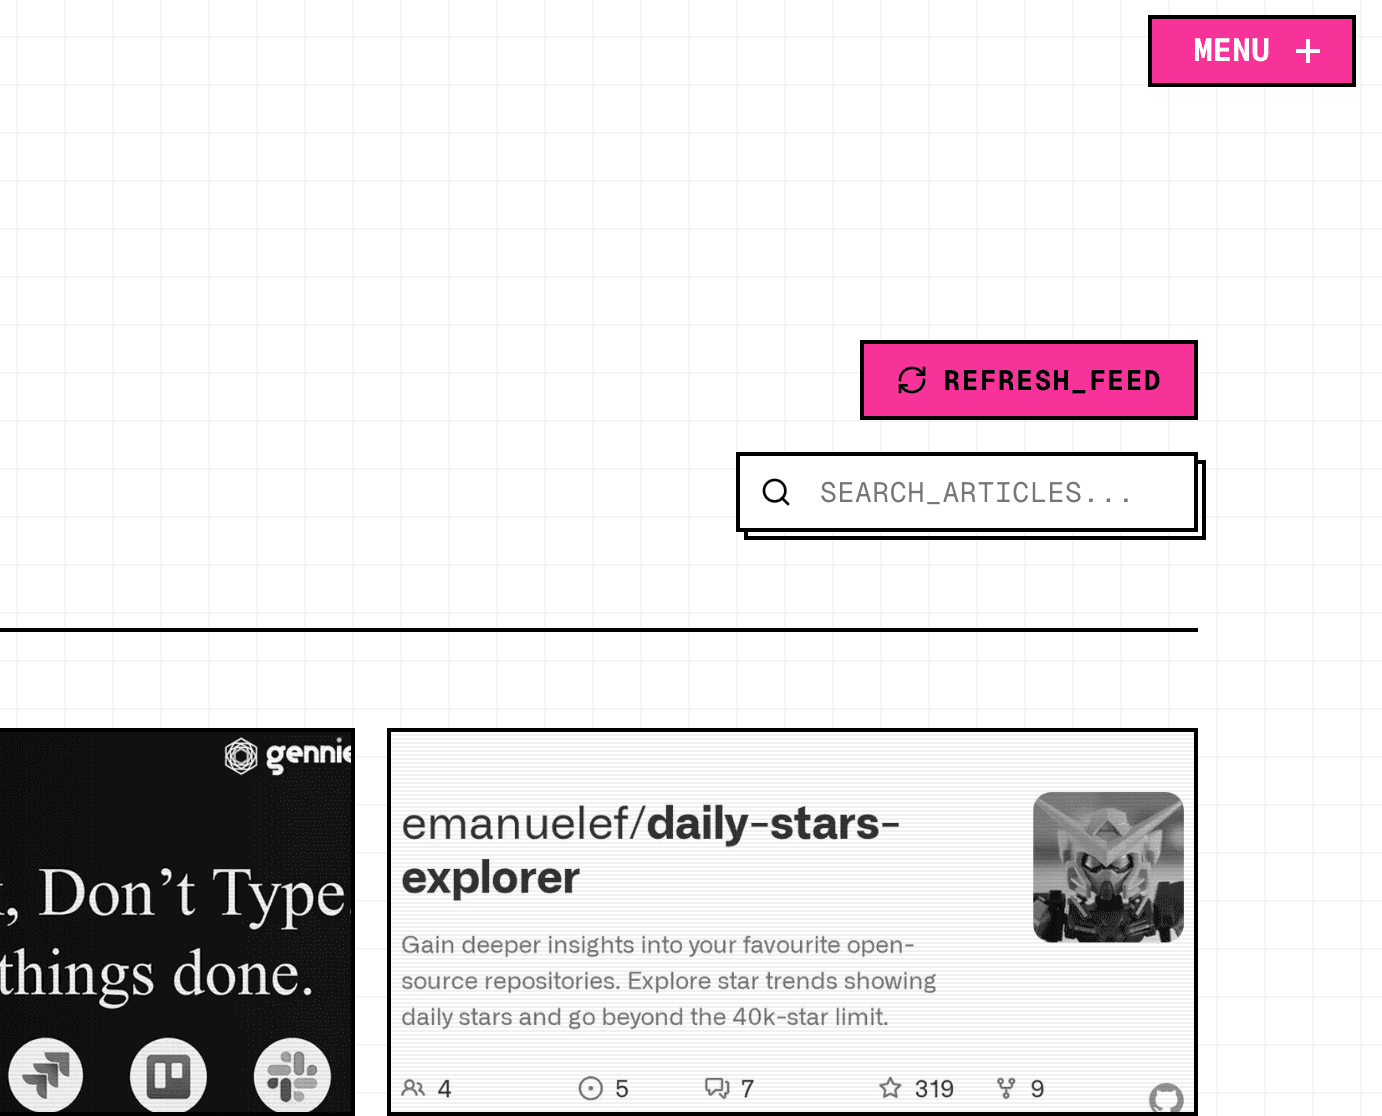
Step 3: Refresh for lastest news or Search for the news you want to read
Next_Steps.exe
Short Term
- Full-text search indices in Postgres.
- Richer categorization (AI, Infra, Frameworks).
- Admin UI to toggle feeds/sources.
Long Term
- Dedicated ingestion worker with retries/DLQ.
- AI-generated summaries instead of truncation.
- User personalization (Saved articles, Email digests).